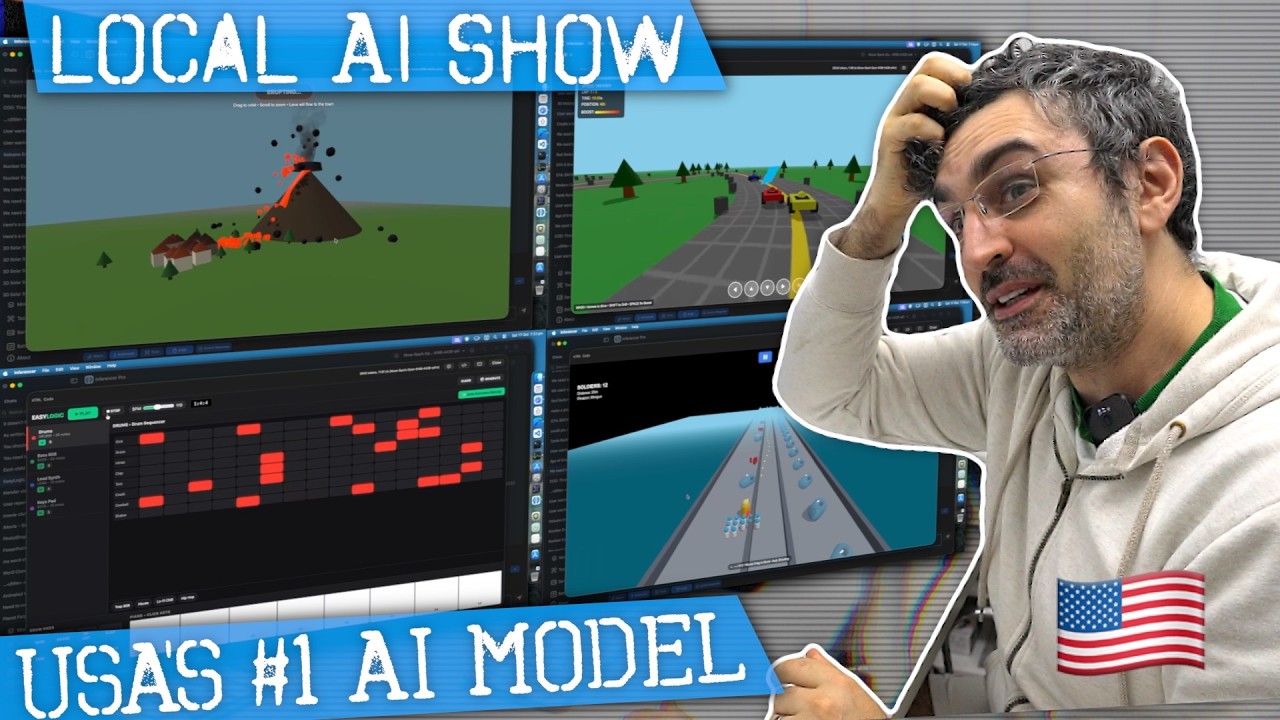
I Ran Meta Spark Open Locally for 24 Hours... USA's #1 Local AI 🫣
Title history
- I Ran Meta Spark Open Locally for 24 Hours... USA's #1 Local AI 🫣 — observed on 20261025-1513 UTC (YouTube)
Keywords
Summary
190 words
Critical Evaluation
Value of the Information & Strength of the Argument
The value of information lies in the extensive hands-on testing and the exposure of real-world caveats of running a large open-weight model locally. The creator systematically tries various coding tasks, providing a representative sample of the model’s strengths (e.g., generating functional 3D scenes) and weaknesses (frequent runtime errors, insufficient context handling, mediocre shader code). However, the argumentation is largely anecdotal; no rigorous comparison with other models under identical conditions is performed, and the creator’s personal bias and informal tone reduce the scientific weight. He does reference benchmark scores but does not critically analyze their validity or reproducibility.
Scientific Rigor, Source Quality, Title Accuracy
The scientific rigor is moderate: the video relies on the creator’s own experiments and informal observations, and no external scientific references are cited. The sources provided in the description are mostly affiliate links to hardware and companion videos, not academic or technical documentation. The title is somewhat misleading: it declares the model as ‘USA’s #1 Local AI’ based on benchmarks, but the content reveals that the practical experience does not always match the lofty claims. The title/content gap is significant enough to potentially disappoint viewers expecting a polished, high-performing model.
202 words
Title / Content Match
The title claims 'USA's #1 Local AI' based on benchmarks, but the video reveals a mixed practical performance with frequent runtime errors and quantization issues; thus the title overpromises relative to the nuanced content.
Quality & Reliability
7/10
The video offers hands-on testing of the Meta Spark Open model across many coding tasks, providing concrete examples and noting both successes and failures. However, the evaluation is subjective, lacks a systematic methodology, and relies on the creator's informal observations rather than controlled benchmarks or peer-reviewed sources.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Overview of Muse Spark 1.3 benchmarks (SWE-bench 75.4) and comparison to other models.
- First JavaScript solar system generation with Q4 quant; shows initial issues.
- Python (Plotly and VPython) solar system generation; multiple working versions.
- First-person spaceship shooter test with shooting and planet destruction.
- Image-based game recreation: screenshot of a Facebook game turned into a playable 3.JS version.
- GTA clone test; capsule-like humans and a flying car with thrusters.
- Final Fantasy VII recreation with intro cutscene and character interaction; limited functionality.
- Flight simulator runtime error and discussion of shader problems.
Cited Sources
- Inferencer — Tool used for quantization and local inference of the model.
- Mac Studio — Hardware used for running the model; affiliate link.
- MacBook Pro — Affiliate link to alternative hardware.
- LG C2 42" Monitor — Affiliate link to display used.
- WD Red Pro HDD — Affiliate link to storage.
- Support — Link to support channel.
- DeepSeek V4.1 — Companion video by the same creator.
- Qwen 4 Exp — Companion video by the same creator.
- Kimi K3 — Companion video by the same creator.
- GLM 5.3 — Companion video by the same creator.
Contribution & Novelties
The video provides a practical, first-hand account of running a large open-weight AI model locally, showcasing its capabilities and limitations in real-world coding tasks. It introduces the use of quantized versions (Q4 and INF) and highlights the memory requirements, offering a realistic preview for enthusiasts. The creator also explores the model’s multimodal aspects and its interactive code generation style, which proposes iterative improvements rather than one-shot full implementations. This contributes to a growing body of community-driven evaluations of open-source LLMs.
Pour aller plus loin :
- Large language model — Provides background on LLMs and their architectures.
- Post-training quantization — Explains the quantization techniques used to reduce model size.
- Local AI inference — Though general, it contextualizes the challenge of running AI models on consumer hardware.
125 words
Radar Profile
The radar profile shows a balanced performance across all dimensions, with high scores in information quantity and technical level, but lower reliability and moderate quality. This indicates a content-rich but not fully rigorous evaluation, typical of hands-on tech reviews.